HPE · Report · 4 pages
What stalls AI inference at the edge
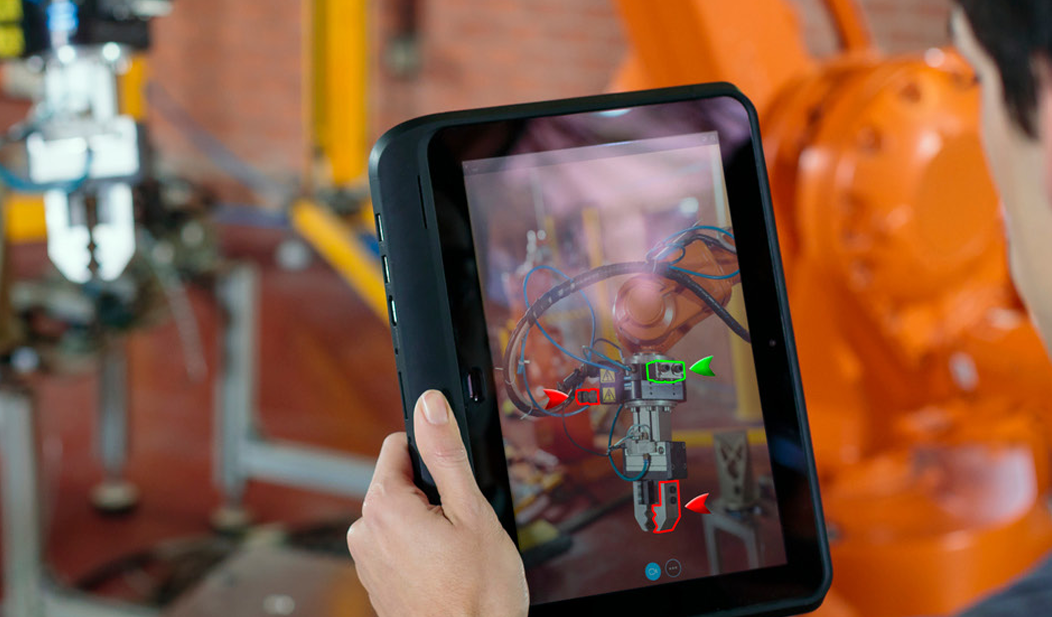
The future of enterprise AI is not about training more models. It is about running inference at the edge, where decisions are made. Quality inspection, predictive maintenance, safety monitoring, and retail engagement all depend on local, fast, and continuous inference. But moving from centralized AI to distributed, real-time decision-making is challenging. Pilots succeed, production environments do not always follow, and the cause is rarely the model. More often, what fails to keep pace is everything around it: the infrastructure running the models, the tools managing that infrastructure, and the governance controlling how changes get made. This report examines the gaps between pilot and production. You’ll learn why they exist, where they show up in practice, and what your organization needs to build deliberately for distributed inference to work at scale.